Maintenance Window Risk and the Nowlan and Heap Patterns
Nowlan and Heap found 89 percent of items had no wear-out zone and 68 percent failed early. What that means for scheduling a maintenance window.
Quick Answer
Nowlan and Heap's 1978 airline study found that 89 percent of items had no wear-out zone, so an age limit could not improve them, and 68 percent showed high failure early in life. It is a different claim from the popular line that 89 percent of failures are random. For software teams it suggests that a batched maintenance window can concentrate risk, so teams should separate clock-driven work from condition-driven work.
A maintenance window is the scheduled time a team takes to patch, upgrade and reconfigure systems. Most engineering organisations hold one without asking if the calendar is the right trigger for the work inside it. A famous 1978 reliability study asks exactly that question, and the usual retelling gets its main number wrong.
In this essay we correct the popular misquote, show the six patterns, map them onto software with the differences named, and give a two-list audit for your own scheduled work. We also say how far the evidence should be trusted.
What the Nowlan and Heap Data Actually Says
A statistic circulates in software circles that 89 percent of failures are random. It is used to explain why uptime is hard to predict. The statistic comes from Reliability-Centered Maintenance by F. Stanley Nowlan and Howard Heap of United Airlines, commissioned by the US Department of Defense.
Reliability sources describe the finding differently, and Wikipedia's entry on reliability-centered maintenance records that the assumption that every component has a fixed lifetime before it must be overhauled "was wrong in nearly every specific example." As Reliability Magazine's summary of Exhibit 2.13 puts it, "Some 89 percent of the items analyzed had no wearout zone at all, which means an age limit could not improve their performance." We read that as a statement about age limits, not about randomness.
| Pattern | Shape of failure probability over age | Share of items |
|---|---|---|
| A | Bathtub shape, with early failures, a flat middle, then wear-out | 4% |
| B | Constant or slowly rising, then pronounced wear-out | 2% |
| C | Gradual increase with no identifiable wear-out age | 5% |
| D | Low when new, a quick rise to a constant level | 7% |
| E | Constant probability at every age | 14% |
| F | High early failure, then constant or very slowly increasing | 68% |
Patterns A and B, the ones with a wear-out region, total 6 percent. Patterns D, E and F, the ones with no wear-out zone, total the 89 percent.
Pattern F Turns a Maintenance Window Into a Risk Event
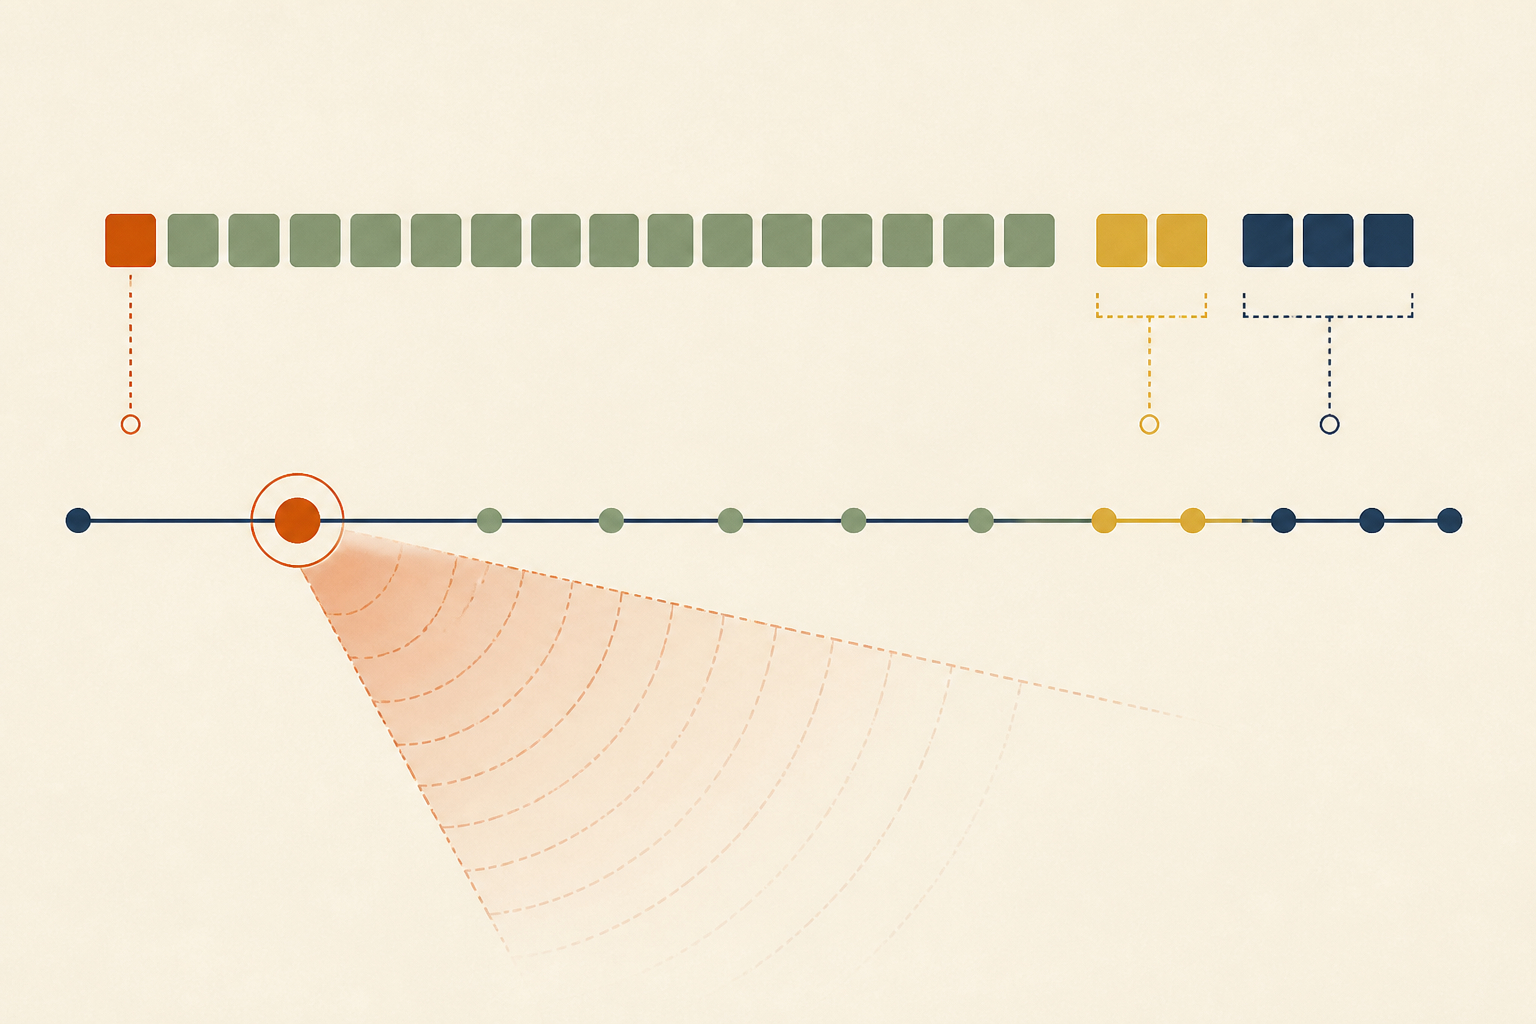
Pattern F is the largest at 68 percent. It describes high infant mortality followed by a constant or very slowly increasing failure probability, so the most dangerous time for such an item is soon after it is new, or after it has been put back into service.
The age axis in these charts is measured from manufacture, overhaul or repair, so each intervention resets the clock. We read that as the key point for operations. If a system behaves like Pattern F, touching a stable system buys no extra reliability and spends some, because it returns the item to its riskiest period.
Key Takeaway. For most items the risk is not that they grow old. It is that they are changed, and the period just after a change is the most dangerous.
The analogy to a software release is direct. A deploy, a configuration push or a dependency upgrade is a shop visit. When we batch these into a maintenance window, we put many shop visits into one night. If incidents cluster on the morning after the window, Pattern F is a reasonable explanation to test before accepting bad luck.
Mapping the Patterns Onto Software, With the Differences Named
Software does not wear out physically. A binary does not rust, and a function does not develop stress fractures, so the wear-out patterns have few direct analogues. A few failure modes do genuinely rise with elapsed time.
- TLS certificates approaching expiry.
- Disk space and log volume consumption.
- Index bloat and decaying planner statistics in databases.
- Credential rotation windows.
- Partition range exhaustion.
Those belong on a calendar, and our notes on certificate expiry monitoring show one of them in detail. Most other work, such as code changes, dependency bumps and migrations, behaves more like Pattern F, where the risk follows the change and not the calendar.
A Two-List Audit of Your Scheduled Work
You can test your own maintenance schedule in an afternoon. Sort every recurring operational task into two lists.
- Clock-based work. Tasks where the probability of failure really rises with time, such as certificate rotation and disk cleanup.
- Condition-based work. Tasks that sit on a calendar out of habit, such as quarterly dependency upgrades and monthly patch windows.
Work on the second list does not become safer because you waited three months to do it. Batching it into one window concentrates the early-life risk at the moment the team is most likely to be tired or thinly staffed. Our guide to canary deployment gates describes how to make each change smaller and observable instead.
The 2026 Version of the Problem
As change frequency rises, the number of resets rises with it. A team shipping four times as often resets the clock four times as often. We think the operational answer is not a more elaborate quarterly review but continuous attention after every change.
Our analysis of configuration drift incidents shows how quiet changes accumulate and surface weeks later, which is the same pattern seen from a different angle.
What Condition-Based Maintenance Requires of Your Monitoring
We think moving from calendar to condition only works if detecting the condition costs less than running the schedule. Aviation got there through instrumentation and non-destructive testing. In software it requires observability that can tell a real regression from noise soon after a change.
Most teams fall back to the calendar because they cannot watch every deploy, configuration change and dependency bump in depth. That is a place where dedicated agents that check errors, performance, security and cost for each connected system can carry some of the load, while engineers decide what to change.
How Far to Trust the Evidence Behind Pattern F
We would hold this evidence with care. Practitioners dispute how far the 1978 conclusions travel. Christopher Jackson, writing on Accendo Reliability, says he cannot put much stock in the way the categories were derived from the engine data, and that even a correct result would not apply directly to an electronics factory or a power plant.
We agree that software is a further step away. The study concerned aircraft components maintained by airlines in the 1970s. We use it as a prompt to test our own incident data for clustering after changes, and not as proof that our systems follow Pattern F.
Test Your Maintenance Window Against Your Own Incidents
The practical step is small. Plot your incidents against the time since the last change to the affected service, and check if they cluster just after maintenance windows. If they do, split the window and move the condition-based work to continuous delivery with monitoring.
We would start with last quarter's incidents. If you want agents to help watch each change, Operate runs dedicated AI agents that investigate production problems with cited evidence and propose fixes for your team to review.
Frequently Asked Questions
We describe it as one of Nowlan and Heap's six failure patterns, showing high infant mortality followed by a constant or very slowly increasing failure probability. In their United Airlines data it covered about 68 percent of items, the largest share of any pattern.
Not as usually stated. The source says about 89 percent of items had no wear-out zone, so an age limit could not improve their performance. We read that as a statement about age-based maintenance, not as proof that failures are random.
They can, in our view, if the work inside them is condition-based and gets batched together. Each change resets an item's age, and items with early-life risk are most likely to fail soon after. We suggest testing this against your own incident timing.
We use it for a failure profile with early failures, a long flat middle and a rise at the end. In the Nowlan and Heap data it was Pattern A, covering about 4 percent of items, which is why we treat it as the exception.
We mean doing maintenance when measured evidence shows a need, instead of on a fixed calendar. In software that means monitoring after changes and acting on observed degradation, while keeping a calendar for the few time-driven items such as certificates.
About the author

Operate Team
The team behind Operate
Operate Team builds Operate, enterprise AI agents for production operations. Operate answers production questions from Slack and Microsoft Teams, investigates alerts, and reviews performance, security and cost. It finds the root cause with evidence and proposes a fix for an engineer to review, with controlled access to your systems.