Incident Severity Levels When the Impact Is Still Unknown
Incident severity levels get declared before impact is known. A procedure to grade from evidence, re-grade on set triggers and audit severity calls later.
Quick Answer
Most teams declare incident severity levels within minutes of detection, before anyone knows how many users are affected. Grading from evidence works better than guessing impact. Read the symptom shape, the blast surface, recent changes, read or write path and what you cannot see, grade to the highest plausible outcome, raise write-path failures one level, and re-grade on set triggers while keeping both the declared and the final level.
Incident severity levels are the ladder a team uses to say how bad an incident is, usually SEV1 for the worst down to SEV3 or SEV4 for minor issues. The level decides who gets paged, how often stakeholders hear from us and how much else stops.
The trouble is timing. Every severity table is written in terms of impact, and at minute two the impact is exactly what nobody knows yet. We think the fix is to declare from evidence and expect to change the level as evidence arrives.
In this post we cover why severity is declared before impact is known, what standard tables assume, how severity differs from priority, five signals available at minute two, re-grading, auditing severity calls, a worked example and when a simple table is enough.
Why Severity Gets Declared Before the Impact Is Known
It is 21:05 and checkout errors jump from a fraction of a percent to several percent in one region. Nothing has been deployed in the last hour. The first responder has to pick a level now, with almost none of the facts the severity table asks for.
Waiting is not the answer. Google's SRE book chapter on managing incidents is direct. "It is better to declare an incident early and then find a simple fix and close out the incident than to have to spin up the incident management framework hours into a burgeoning problem."
The same chapter gives simple triggers for declaring at all, such as needing a second team, an outage visible to customers, or a problem still unsolved after an hour of focused analysis. Those triggers say when to declare. They do not say which level to choose, and that is the gap we fill with evidence.
What Standard Severity Tables Assume About Impact
Most severity tables are a function of impact. A typical ladder says SEV1 means a core service is down for everyone, SEV2 means major degradation, and SEV3 means a partial or minor problem. ITIL-style matrices combine impact with urgency to reach a priority.
In our reading, all of them assume the inputs are known. Their worked examples are written in the past tense, which makes them good for labelling an incident afterwards and weak for grading one in progress.
Some scoring systems build uncertainty in. CISA's National Cyber Incident Scoring System scores categories that include functional impact, recoverability and potential impact, and uses the score to prioritise "limited incident response resources." Potential impact and recoverability are the parts most software ladders leave out.
Severity and Priority Answer Different Questions
We keep severity and priority separate, because mixing them causes arguments in the incident channel. The table below shows the distinction we use.
| Question | Severity | Priority |
|---|---|---|
| What it measures | How much damage the failure is doing | How soon this work should happen relative to other work |
| Who sets it | The incident commander, from evidence | Whoever owns the queue the work sits in |
| Example of divergence | An internal tool fully broken while its users are away is high severity | The same tool can wait, so its priority is low |
A high severity usually means a high priority, but not always. We let each answer its own question rather than forcing one number to do both jobs.
Five Signals That Set Incident Severity Levels at Minute Two
We cannot count affected users at minute two, but we can read five kinds of evidence. Each one narrows the range of plausible outcomes.
1. Symptom Shape
A step change, where errors jump from near zero to a high rate at once, points to a hard failure or a configuration flip. A slow creep points to exhaustion of something, such as memory, connections or a queue. Step changes usually justify a higher initial grade, because they rarely fix themselves.
2. Blast Surface
We cannot count users, but we can count entry points. One endpoint, one region, one tenant or one background worker each bound the possible damage differently, and bounding the surface bounds the risk.
3. Change Proximity
A deploy, flag flip, configuration push or infrastructure change inside the window is the highest-information fact available, because it gives an immediate rollback option. Its absence matters too. With no internal change, an upstream provider moves up the suspect list, which we cover in the upstream outage triage protocol.
4. Reversibility
A read-path failure stops hurting the moment it is fixed. A write-path failure, such as orders saved wrongly or payments recorded twice, leaves data that has to be reconciled afterwards. We grade write-path failures one level higher because the damage keeps compounding after the fix.
5. What We Cannot See
If there is no metric for the depth of a queue, the state of a second region or the correctness of what is being written, the worst case cannot be ruled out. Blind spots raise the grade until they are closed.
Gathering these five signals by hand takes time the responder does not have, because they live in deploy history, dashboards, logs and the database. Pulling them together is the kind of work automated root cause analysis does well, leaving the human to make the call.
From the signals we apply one rule, in three steps.
- Grade to the highest plausible outcome consistent with the current evidence.
- Raise the grade one level if the failure is on a write path.
- State in the first update that impact is not yet known and which signal set the grade.
Re-Grading Is the Practice, Not the Exception
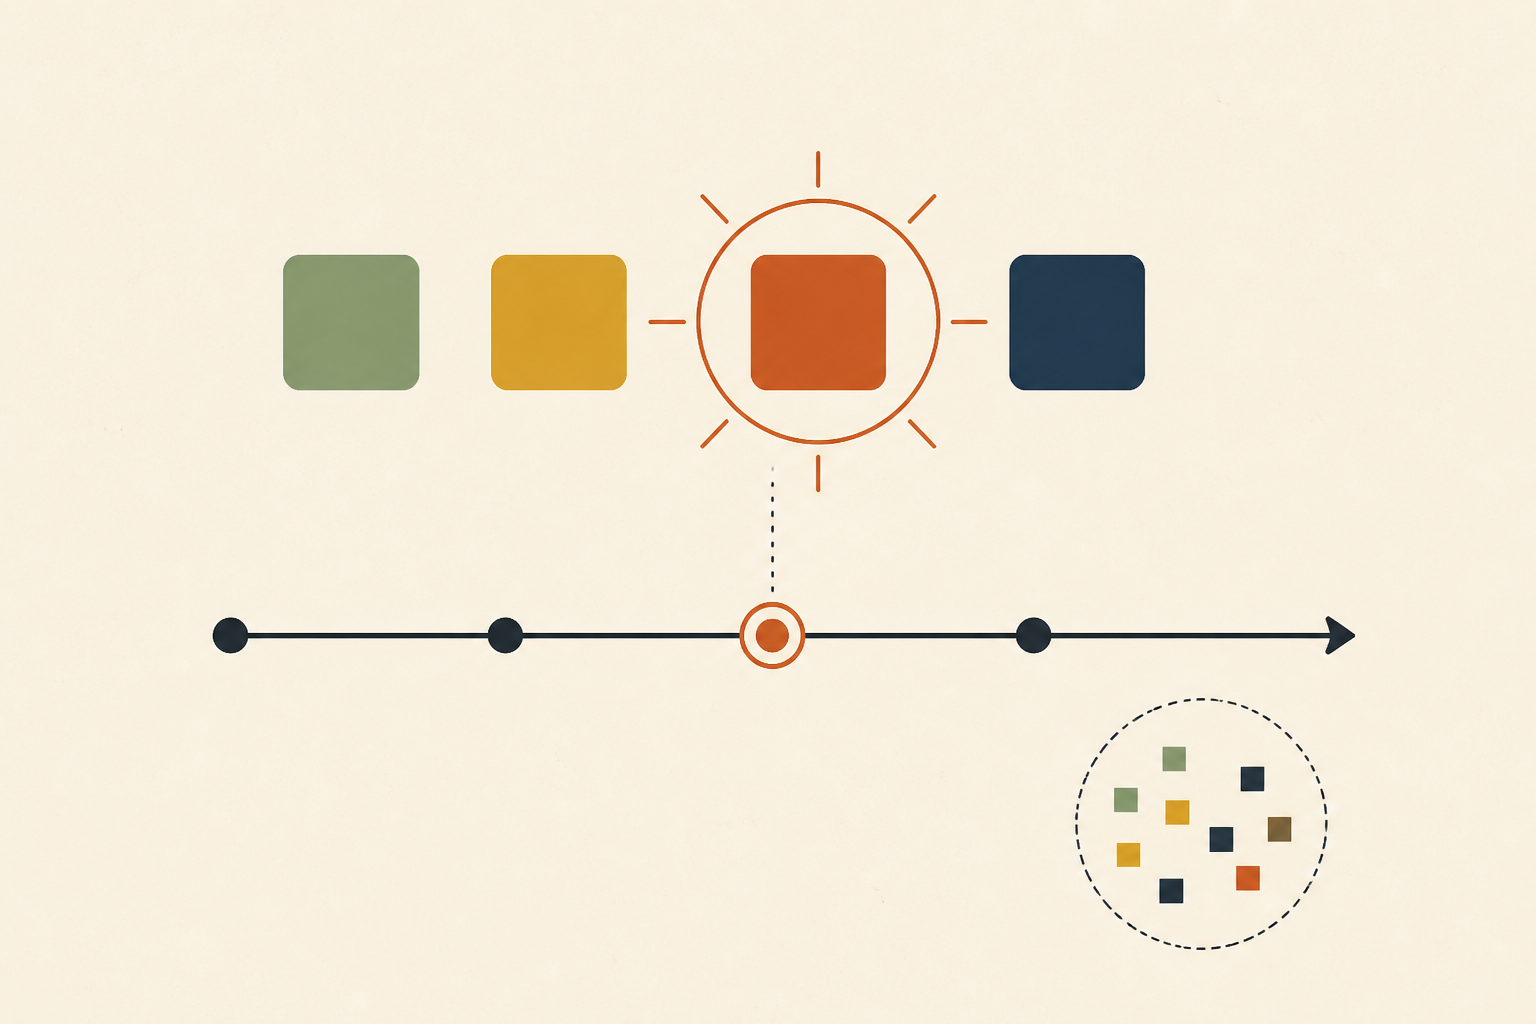
A level declared from partial evidence should move as evidence arrives. The SRE workbook chapter on incident response lists "Declare incidents early and often" among its basic principles, and early declaration only works if re-grading is normal.
We set explicit triggers so re-grading is not left to mood.
- The blast surface grows, for example a second region or tenant starts failing.
- A cause is confirmed, which usually tightens the range in one direction.
- A fixed time box expires, such as every fifteen minutes during the first hour.
We record both the declared level and the final level. The gap between them is the only measure of how well a team reads early evidence, and it disappears if people overwrite the original.
Audit Severity Calls After the Incident
Severity calls improve only when someone looks at them afterwards. We track three numbers.
- Under-declaration rate, how often the final level was higher than the declared one.
- Time to first re-grade, how quickly the team moves from guessing to knowing.
- Over-declaration ratio, how many top-level incidents were downgraded within minutes.
Too much over-declaration teaches people to ignore the top level, and too much under-declaration delays help. Escalations have the same problem, which we examine in escalation metrics.
A Worked Example From a Checkout Error Spike
The timeline below is illustrative, built from the 21:05 scenario above, to show how the rule plays out.
- 21:05, errors jump on checkout, a step change on a write path with no recent deploy. We declare SEV2 as the highest plausible outcome and say impact is not yet known.
- 21:15, logs show every error comes from one payment provider integration. The surface is bounded, so we hold SEV2.
- 21:25, the provider's own status page confirms a change on their side. Change proximity now points upstream.
- 21:30, traffic data shows that provider carries a small share of checkouts, and no orders were written wrongly. We re-grade to SEV3 and keep the original SEV2 on record.
Coordination matters as much as the grade. Who commands the response and how far one person's span of control reaches is covered in incident command doctrine.
When a Simple Severity Table Is Enough
We do not push this procedure on every team. When the whole product is down, the grade is obvious and the signals add nothing.
Small teams with one service and one on-call engineer may also get more from clear declaration triggers than from a grading procedure. Regulated environments often define severity in contracts or rules, and those definitions win over any internal method.
Alert design is the other half of the problem. A team flooded with low-value pages will grade poorly whatever its table says, which is why we treat alert fatigue triage as part of the same work.
Grade Incident Severity Levels From Evidence, Then Re-Grade
We would add the five signals and the three-step rule to the incident template, record declared and final levels separately, and review the gap every month. That turns incident severity levels from a guess about impact into a decision anyone can audit.
When the evidence behind a grade is scattered across systems, Operate can help gather it. It brings the evidence from logs, databases and code together through read-only adapters, and proposes any code fix as a patch file an engineer reviews and applies.
Frequently Asked Questions
There is no universal standard, but many teams use four levels. We typically see SEV1 for a critical outage affecting most users, SEV2 for major degradation, SEV3 for a partial or minor problem, and SEV4 for cosmetic issues or ones with a workaround. Each team should define its own thresholds.
It is a label for how much damage an incident is doing to users and the business. We use it to decide who responds, how quickly and how often stakeholders are updated. Because impact is rarely clear early on, we set the first level from evidence and expect to change it.
We assess it from the evidence available at the time, such as the shape of the symptoms, which parts of the system are affected, recent changes, and if data is being written incorrectly. We grade to the worst plausible outcome, then re-grade as the actual impact becomes clear.
Severity measures how much damage a failure is doing. Priority sets the order in which work gets done relative to everything else. We usually see them move together, but a fully broken tool nobody needs this week can be high severity and still low priority.
It is a table that maps conditions such as scope, user impact and urgency to a severity level, often with response expectations for each level. We find matrices useful for consistency, but they assume impact is known, so we pair them with rules for grading under uncertainty.
About the author

Operate Team
The team behind Operate
Operate Team builds Operate, enterprise AI agents for production operations. Operate answers production questions from Slack and Microsoft Teams, investigates alerts, and reviews performance, security and cost. It finds the root cause with evidence and proposes a fix for an engineer to review, with controlled access to your systems.