Incident Case Definition Lessons From Disease Outbreak Work
Outbreak investigators define who counts as a case before hunting for the cause. Incident channels skip that step, and the blast radius pays for it.

Quick Answer
A working case definition states who counts as affected, using objective criteria restricted by time, place and person, before the team looks for the cause. It must not contain the suspected cause, or the investigation can only confirm what it already believes. Outbreak investigators make this step four of thirteen. Incident teams can adopt a ninety-second version covering symptoms, window, surface, cohort and three tiers of certainty.
In a live incident, communication often breaks down at the level of the count. One engineer reports two hundred affected customers from an error log, while a support lead says the whole EU region is degraded because the queue is rising. Both may be right, and neither has written down a case definition.
The cost is predictable. The team spends the first hour talking past each other, and the true scale of impact is revised upward days later in the postmortem. We think field epidemiology has a cleaner answer than most incident templates do.
Two People in the Channel Counting Different Things
When nobody states who counts as affected, we only see the failures we were already looking for. An agreed definition is a shared yardstick, and it makes counts comparable between engineers, support and management.
The rest of this essay explains how outbreak investigators do it, lists the mistakes software teams make, and gives a short template for the incident channel.
Step Four of Thirteen in an Outbreak Investigation
The CDC's Principles of Epidemiology lists thirteen steps for investigating an outbreak. Step three verifies the diagnosis, step four constructs a working case definition and step five finds cases systematically.
The document says the case definition consists of clinical criteria restricted by time, place and person, and it should use simple, objective measures. In software we often go from knowing something is wrong straight to finding every error, skipping the step that says what an error is.
The CDC's Field Epidemiology Manual adds a caution that suits incident work. The steps might be conducted out of order or concurrently, though none should be skipped.
Your Case Definition Must Not Contain Your Theory of the Cause
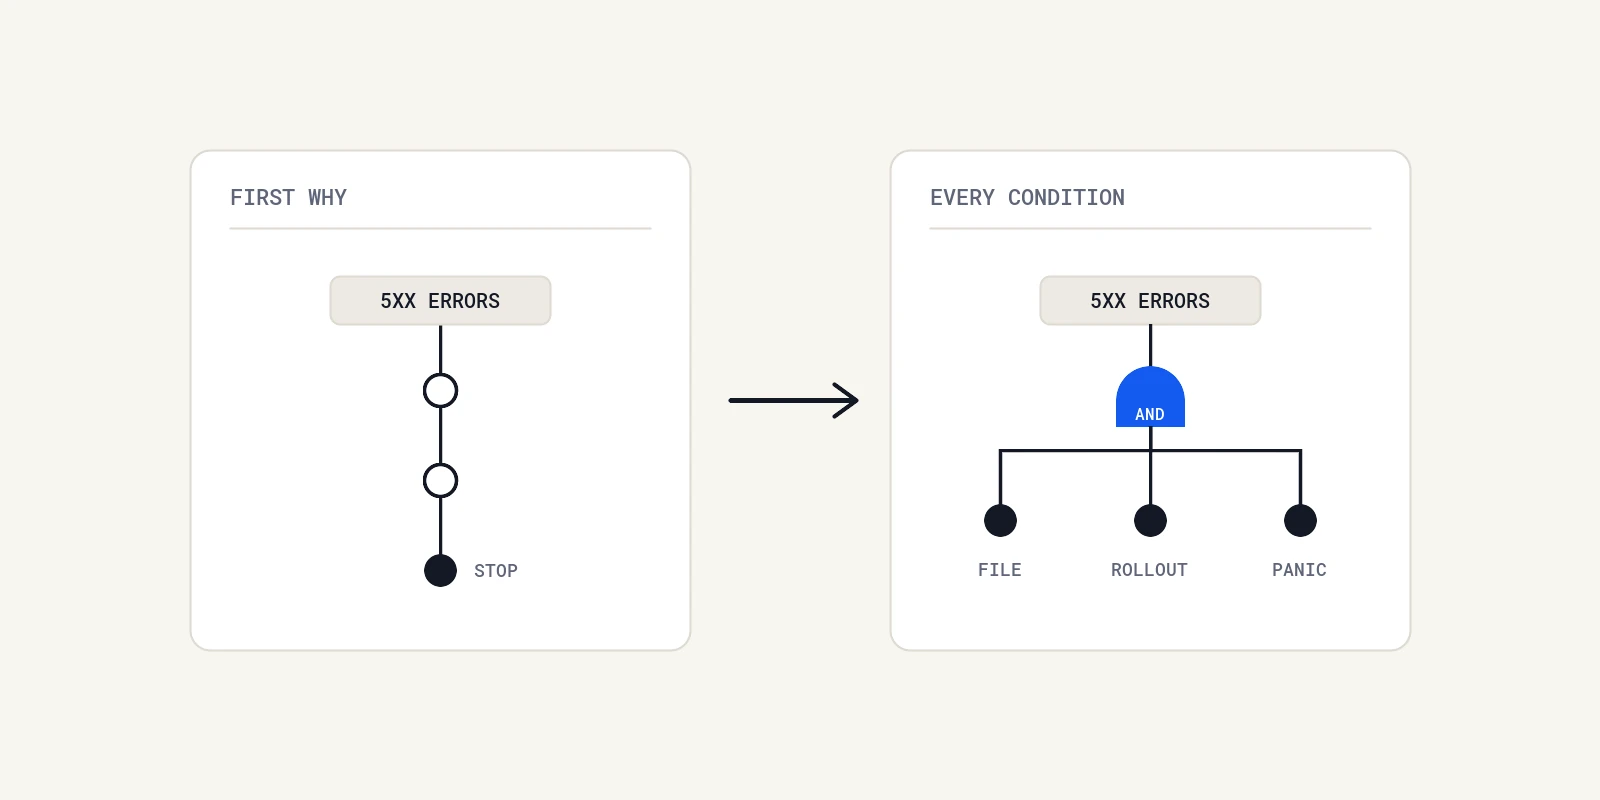
The most common mistake, in epidemiology and in engineering, is baking the suspected cause into the definition of the victim. The CDC material uses a salad bar example. If you suspect one salad bar, the case definition should not be illness among people who ate there. It should be illness among anyone in the facility, and you then test if those who ate at the salad bar were at higher risk.
We make the same error whenever we define an incident as checkout errors caused by the 14:02 deploy. If the definition is the deploy, you only pull the logs for that deploy. Anything that failed for another reason, or began at 13:55, is excluded by definition.
Key Takeaway. Defining an incident by its suspected cause makes the investigation circular, because it ignores every data point that does not fit the first theory.
The better definition is failed checkouts between 14:00 and 15:30. You then test if the deploy cohort failed at a higher rate than the rest. The postmortem can then confirm or reject the deploy, since the dataset was not curated to confirm it.
Confirmed, Probable and Possible Tiers
Epidemiologists use tiers because diagnosis is uncertain early on. The CDC text describes confirmed cases as those with laboratory verification, probable cases as those with clinical features but no confirmation, and possible cases as those with fewer features.
Software incident channels often have exactly one tier, which is confirmed. A request that does not throw an error is counted as not affected, which understates the blast radius. We would add probable cases, such as requests with very high latency, and possible cases, such as all active sessions in the window.
Start Loose and Tighten Later
We follow the CDC material, which advises using a loose definition in the early stage of an investigation, including possible cases, and tightening it later for analytical work so false positives do not distort the results.
Teams often do the opposite. They start with the specific error message they saw and never widen their view, then get surprised when a second report arrives from another region. Starting narrow makes sense only when you already know what you are looking for.
Check Your Instruments Before You Believe the Spike
Verifying the diagnosis is step three for a reason. An apparent rise in cases can come from a change in how cases are counted. The software equivalent is a spike that is a measurement artefact, and we would spend ninety seconds checking the instruments first.
- Did a metric sampling rate change?
- Was a logging library upgraded recently?
- Did someone change a dashboard timezone or a metric name?
- Was an alert threshold edited?
Skipping this check can cost hours spent investigating a ghost incident caused by a change in how we count and not a change in what is happening.
Time, Place and Person for Incident Scope
A robust case definition needs three dimensions that most incident scopes leave out.
- Time. A defensible start for the window, not just when the alert fired.
- Place. The affected surface, such as a region, shard, availability zone or client version.
- Person. The affected cohort, such as tenants, plans or device classes.
An incident scope that says checkout is down is not useful. One that says internal server errors on the mobile web surface in one region for enterprise tenants after a stated start time is a working case definition. Our guide to incident severity levels when impact is still unknown uses the same idea to rate severity honestly.
Collect the Perishable Evidence While You Can
Field investigators are urged to obtain specimens before they are discarded. The Field Epidemiology Manual describes obtaining microbiologic strains already isolated before they are thrown away, so they remain available if new questions arise.
In software, the most valuable evidence often evaporates once service is restored. Connection states, queue depths and logs about to rotate disappear. If the case was not defined broadly enough to capture them during the incident, the postmortem is written from what survived and not from what mattered. Our notes on how postmortems record the answer and lose the search look at the same loss afterwards.
The Ninety-Second Version for a Live Incident
You do not need thirteen steps during a page. You need a short pause to post a structured message in the channel.
- Working definition. The symptoms observed, for example 504 gateway timeouts.
- Excluded cause for now. No mention of a deploy or a database in the definition.
- Time, place and person. The start time, the region or service and the user cohort.
- Tiers. Confirmed, probable and possible, each with a stated criterion.
Agreeing that message takes less time than the argument it prevents. It also gives an incident commander a fixed scope to report against. Google's SRE book says in its chapter on managing incidents that "The incident commander's most important responsibility is to keep a living incident document", and the case definition belongs at the top of it. Our analysis of the incident commander doctrine software only half borrowed covers the rest of the role.
Where the Epidemiology Analogy Stops
Outbreak investigations run for weeks, and software incidents are often resolved in minutes. The CDC itself notes that steps may be done concurrently or out of order in urgent situations. We are not suggesting that engineers become epidemiologists.
The narrower claim is that defining the population before hunting for the cause separates an investigation that finds the truth from one that validates a guess. The step is often skipped because the person who must write the definition is also the person trying to restore service. That is a place where dedicated AI agents that investigate with cited evidence can help, by gathering evidence across the whole affected population while a person owns the definition.
Write the Case Definition Before You Chase the Cause
A case definition costs ninety seconds and removes a class of circular investigations. State the symptoms, the window, the surface and the cohort, keep the suspected cause out, and widen the net before narrowing it.
We would try it in the next incident channel and compare the early scope with the postmortem number. When you want help collecting evidence for the full affected population, Operate runs dedicated AI agents that investigate production problems with cited evidence and propose fixes for your team to review.
Frequently Asked Questions
We use the epidemiology meaning, which is a set of simple, objective criteria, restricted by time, place and person, that decides who counts as a case. In incident response it decides which users, requests or tenants count as affected.
If the definition contains the suspected cause, the investigation can only find cases that fit that cause. We define the affected population by symptoms, then test whether the suspected cause explains a higher rate of failure.
We take them from the CDC's tiers. Confirmed cases have laboratory verification, probable cases have clinical features without confirmation and possible cases have fewer features. In incidents they map to errors, high latency and all sessions in the window.
We write down the symptoms, then the time window, the place such as region or service, and the person cohort such as tenants or plans. We keep the suspected cause out and update the definition when new evidence arrives.
We start loose to find the extent of the problem and tighten later for analysis. The CDC material makes the same point. A narrow start tends to miss cases that come from other regions or services.
About the author

Operate Team
The team behind Operate
Operate Team builds Operate, enterprise AI agents for production operations. Operate answers production questions from Slack and Microsoft Teams, investigates alerts, and reviews performance, security and cost. It finds the root cause with evidence and proposes a fix for an engineer to review, with controlled access to your systems.